


Research Group

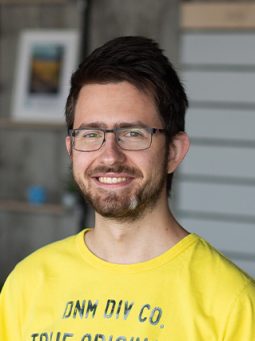
Branislav Pecher
Research areas: Learning with limited labelled data, Large language models, Auditing social media platforms, Few-shot learning, Mechanistic interpretability of LLMs
Position: Researcher
Branislav has expertise in artificial intelligence, machine learning and natural language processing, with a specific focus on learning with limited labelled data and low-resource settings. In this domain, during his doctoral studies, he mainly focused on a rigorous investigation how sensitive the approaches for learning with limited labelled data are to non-deterministic decisions, such as random seeds or sample selection that are often overlooked but may have significant effects. Currently, his focus has expanded in two directions. The first is evaluation and understanding of vulnerabilities and capabilities of large language models – through mechanistic understanding of what is actually happening inside these models. The second direction is auditing of social media platforms for potentially harmful behaviour – such as spreading misinformation, enclosing users in filter bubbles, or negatively affecting minors.
He has co-authored more than 20 papers that were accepted to top journals (ACM Computing surveys) or top-tier conferences in AI and NLP (including, EMNLP, ACL, SIGIR or RecSys). Together, these publications have more that 440 citations, resulting in a h-index of 11 (according to Google Scholar, as of 2026/04). He has also been involved in multiple projects, including AI-Auditolog, VeraAI, or TAILOR. This included international research collaborations, with universities such as Bar Ilan University or Eindhoven University of Technology.
PhD topic: Addressing effects of randomness on the stability of learning with limited labelled data
Supervising team: Mária Bieliková (KInIT), Ivan Srba (KInIT)
Learning with limited labelled data, including but not limited to concepts such as zero/few-shot learning, transfer learning or meta-learning, aims to effectively train a model while using only a small amount of labelled samples. Although such approaches were successfully applied in many domains, they are especially sensitive to the effects of uncontrolled randomness caused by non-determinism in the training process. The non-determinism negatively affects the stability of the trained models and leads to large variance in results across training runs. Such uncontrolled randomness can unintentionally, but unfortunately also intentionally, create an imaginary perception of research progress. When disregarded, the randomness can prohibit objective comparison of new methods, leading to overestimation, or in some cases underestimation, of their performance. Even though a growing number of studies focus on addressing the negative effects of randomness on stability, the research is still limited in its extent, facing many problems and inconsistencies.
Our aim in this work is to deal with the drawbacks when addressing the effects of randomness in learning with limited labelled data. Based on a comprehensive survey, we identify the most significant open problems, specifically the focus on investigation only on a small fragment of randomness, disregard for the interactions between sources of randomness and an absence of effective mitigation strategies. As a part of preliminary experiments, we design a general methodology for investigating effects of randomness. We apply this investigation methodology to determine the importance of multiple sources of randomness in meta-learning and language model fine-tuning. The preliminary results revealed a significant impact of randomness originating from splitting of data and selecting what data is labelled, which are mostly ignored in current research.
Selected achievements
- Award for excellent dissertation thesis on the topic of “Sensitivity of Learning with Limited Labelled Data to the Effects of Randomness”
- Placed first in 6 out of 9 languages within SemEval Task 3 Subtask data challenge focused on detection of persuasion techniques (team name KInIT). Placed 2nd, 3rd and 4th in the remaining languages, becoming the most successful team. The task that was addressed is a complex multi-class multi-label classification with 23 classes and with 3 surprise languages (in a zero-shot setting).
- Best Paper award at RecSys 2021 conference (the awarded full paper)
- Rector’s Award for Excellent Study Results during Masters’ Programme, 2019, Slovak University of Technology
- Rector’s Award for the Best Student of Master Study for the Academic Years 2017/18, 2018/19, Slovak University of Technology
Selected activities
- Invited as a speaker to the Mind&Tech conference, where I presented on the topic of auditing of social media platforms
- Invited as a speaker with a topic of AI and large language models, their capabilities, vulnerabilities and how to use them, at multiple occasions, including: presentation at Basta Digital, FF UKF in Nitra, or NerdNITE
- Research visit at Eindhoven University of Technology (duration of 3 months from August until September 2023) which was supported through the TAILOR Collaboration Exchange Fund, which I summarised as a blog post
- Attended multiple conference, including EACL’25, ACL’25, EMNLP(’24 and ’25), SIGIR’25, IJCAI-ECAI’22, RecSys’21, ECML-PKDD’20
- Participated in the Eastern European Machine Learning Summer School 2022 and 2023
- Attended RecSys’21 conference and presented the paper “An Audit of Misinformation Filter Bubbles on YouTube: Bubble Bursting and Recent Behavior Changes”, the paper won Best Paper Award
- Volunteering activities at the EMNLP’24, IJCAI-ECAI’22, RecSys’21 conferences
Professional service
Reviewer for journals:
- Pattern Recognition (Elsevier)
Reviewer at multiple conferences, including:
- International Conference on Machine Learning (ICML)
- Annual Conference on Neural Information Processing Systems (NeurIPS)
- International Conference on Learning Representations (ICLR)
- ACL Rolling Review (includes ACL, EMNLP, EACL, NAACL)
- ACM Conference on Recommender Systems (RecSys)
- International ACM SIGIR Conference on Research and Development in Information Retrieval (SIGIR)
Selected Projects

Selected Publications
A Survey on Stability of Learning with Limited Labelled Data and its Sensitivity to the Effects of Randomness
Pecher, B., Srba, I., Bielikova, M. Learning with limited labelled data, such as prompting, in-context learning, fine-tuning, meta-learning or few-shot learning, aims to effectively train a model using only a…
Comparing Specialised Small and General Large Language Models on Text Classification: 100 Labelled Samples to Achieve Break-Even Performance
When solving NLP tasks with limited labelled data, researchers typically either use a general large language model without further update, or use a small number of labelled samples to tune…
An Audit of Misinformation Filter Bubbles on YouTube: Bubble Bursting and Recent Behavior Changes
The negative effects of misinformation filter bubbles in adaptive systems have been known to researchers for some time. Several studies investigated, most prominently on YouTube, how fast a user can…
Revisiting Algorithmic Audits of TikTok: Poor Reproducibility and Short-term Validity of Findings
Social media platforms are constantly shifting towards algorithmically curated content based on implicit or explicit user feedback. Regulators, as well as researchers, are calling for systematic social media algorithmic audits…