


Research Group

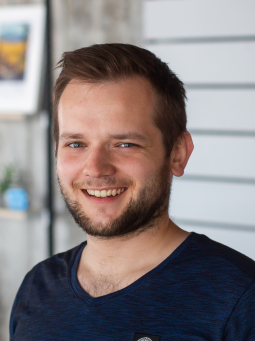
Ján Čegiň
Research areas: Natural language processing, Large language models and text augmentation, Human-in-the-loop machine learning, Crowdsourcing and adversarial example generation, Human-computer interaction, Low-resource machine learning and classification
Position: Researcher
Ján focuses on natural language processing, machine learning, crowdsourcing, and the interaction between humans and large language models. His research primarily investigates how human-inspired approaches and large language models can be combined to improve data augmentation, robustness, and downstream model performance in low-resource settings.
He obtained his Master’s degree in Intelligent Software Systems from the Slovak University of Technology in Bratislava, graduating with honors (cum laude). During his studies and research career, he participated in projects in collaboration with both academia and industry partners, including Continental Automotive Systems, focusing on malware detection, reinforcement learning, and automated test data generation.
Currently, his research focuses on LLM-based text augmentation, adversarial example generation, and human-in-the-loop approaches for natural language processing. In his PhD research, supervised by Jakub Šimko (KInIT) and advised by Peter Brusilovsky (University of Pittsburgh), he investigated how large language models can complement or replace traditional crowdsourcing approaches for generating diverse and robust training data. He successfully defended his PhD in 2025. His work explores the trade-offs between cost, diversity, robustness, and effectiveness of human-generated versus LLM-generated augmentations.
His recent research demonstrates that large language models can generate highly diverse and valid textual augmentations while significantly reducing costs compared to traditional crowdsourcing approaches. He also studies how human-inspired prompting strategies, sample selection methods, and diversity incentives influence downstream classification performance and robustness, in particular for low-resource languages.
Ján has co-authored publications at leading NLP and AI conferences, including ACL, EMNLP, and NAACL. His research interests bridge natural language processing, machine learning, and human-computer interaction, with a strong focus on practical and human-centered AI systems.
PhD topic: Machine learning with human in the loop in the era of LLMs
Supervising team: Jakub Šimko (KInIT), Peter Brusilovsky (University of Pittsburgh)
The rapid advancements in large language models (LLMs) have sparked interest in their potential
to enhance data augmentation processes, particularly compared to traditional human-driven methods
like crowdsourcing. This thesis investigates the integration of LLMs into textual augmentation,
addressing how LLM-based augmentation compares to human-centred approaches regarding cost,
performance, and effectiveness. Our research addresses four central questions: (1) the efficacy of
LLMs versus human workers in data augmentation tasks, (2) the transferability of human computation
techniques to LLM prompting, (3) the cost-benefit analysis of LLM-based augmentation
compared to traditional methods, and (4) the impact of sample selection strategies on downstream
model performance when using LLMs. Through extensive experimentation, we demonstrate that
LLMs can generate more diverse and valid textual data than human workers while significantly reducing
costs. Additionally, incorporating human-inspired prompting techniques, such as hints and
chaining, can improve model performance, although the impact on lexical diversity remains limited.
Our findings also reveal that LLM augmentation is particularly beneficial in low-resource settings
where only a few seed samples are available. Furthermore, we evaluate various sample selection
strategies and find that random sampling remains a strong baseline, while hint-based strategies
yield the best results for out-of-distribution performance. The results of this thesis highlight the
potential of LLM-based textual augmentation to surpass traditional methods under specific conditions
and pave the way for more efficient and cost-effective data augmentation practices in the era
of advanced language models.
Selected achievements
- Graduated with honors (cum laude) from the Slovak University of Technology in Bratislava
- Member of the excellence team PeWe at the Slovak University of Technology in Bratislava led by prof. Mária Bieliková
- Co-authored publications accepted to leading conferences in NLP and AI, including ACL, EMNLP, and NAACL
- Participated in collaborative research projects with academic and industry partners in AI, cybersecurity, and intelligent systems
Selected activities
- Speaker and participant at research-oriented AI and NLP events and conferences
- Research and development in adversarial robustness and human-in-the-loop machine learning
- Participation in projects focused on misinformation detection, smart systems, and AI-assisted data generation
- Collaboration on interdisciplinary projects combining NLP, crowdsourcing, and human-centered AI
Professional service
Reviewer at multiple conferences, including:
- ACL Rolling Review (includes ACL, EMNLP, EACL, NAACL)
- ACM Conference on Recommender Systems (RecSys)
Selected Projects

Selected Publications
Effects of diversity incentives on sample diversity and downstream model performance in LLM-based text augmentation
Cegin, J., Pecher, B., Simko, J., Srba, I., Bielikova, M., and Brusilovsky, P.1 1 University of Pittsburgh, Pittsburgh, USA The latest generative large language models (LLMs) have found their application…
ChatGPT to Replace Crowdsourcing of Paraphrases for Intent Classification: Higher Diversity and Comparable Model Robustness
The emergence of generative large language models (LLMs) raises the question: what will be its impact on crowdsourcing? Traditionally, crowdsourcing has been used for acquiring solutions to a wide variety…
LLMs vs Established Text Augmentation Techniques for Classification: When do the Benefits Outweight the Costs?
Social media platforms are constantly shifting towards algorithmically curated content based on implicit or explicit user feedback. Regulators, as well as researchers, are calling for systematic social media algorithmic audits…
RoSE: Round-robin Synthetic Data Evaluation for Selecting LLM Generators without Human Test Sets
LLMs are powerful generators of synthetic data, which are used for training smaller, specific models. This is especially valuable for low-resource languages, where human-labelled data is scarce but LLMs can…