


Research Group

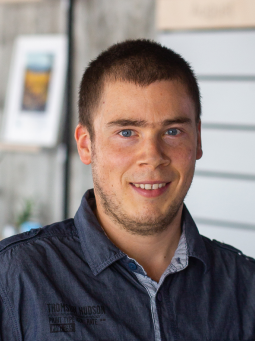
Miroslav Blšták
Research areas: natural language processing, data processing, computational linguistics, linguistics resources, computer-assisted learning
Position: AI Specialist
Miroslav specializes in Natural Language Processing (NLP), combining linguistic approaches with machine learning. He has developed numerous tools, lexicons, and knowledge sources for text processing, with a primary focus on Slovak as a low-resource language. His expertise covers a broad spectrum of NLP tasks, including named entity recognition, concept extraction, text reconstruction, and sentiment analysis. Additionally, he focuses on developing morphological and lexical analysis tools for the Slovak, applicable in virtual assistants and other systems that rely on text analysis.
Beyond his research in NLP, he has a long-standing interest in computer-assisted learning, where his doctoral research focused on automatic question generation. He has been actively involved in developing interactive educational applications and games that leverage information technology to enhance the learning experience.
During his tenure at the Slovak University of Technology, Miroslav mentored over 20 Bachelor’s and Master’s students in the field of NLP. He was also deeply involved in delivering specialized courses and seminars on text processing, business process modeling, and software architecture.
Selected activities
- Member of Ethics Committee
Selected Projects


Other notable projects

Selected Publications
Automatic question generation based on sentence structure analysis using machine learning approach
Blstak, M., Rozinajova, V. Abstract: Automatic question generation is one of the most challenging tasks of Natural Language Processing. It requires “bidirectional” language processing: firstly, the system has to understand…
Selected Student Supervising
Master
- Lukáš Radoský – Similarity of short texts in Slovak language. Defended 2021
- Simona Zelenčíková – Coreference resolution in text. Defended 2021.
- Martin Grega – Temporal sequence identification in the text. Defended 2021.
- Richard Galeštok – Automated analysis of sentiment in Slovak texts. Defended 2020.
- Lukáš Belaj – Named entity extraction from Slovak text. Defended 2019.
- Lukáš Miškovský – Identification of coreference links in text. Defended 2017.
Bachelor
- Michal Hunák – Detecting tricky plagiarism. Defended 2020.
- Juraj Gemeľa – Building a Dictionaries by Games. Defended 2019.
- Ondrej Harnúšek – Tool for determining similarity of texts. Defended 2019.
- Lukáš Radoský – Lexicon construction using games. Defended 2019.
- Tomáš Gábrš – Question generation from educational text. Defended 2017.
- Martin Nemček – Educational texts processing. Defended 2016.